Engineering · 2026.10.10 · 5 min
A Full-Site Redesign: AI Scores Make a Bad Gate, So Swap Tokens First and Rework Layouts Later
EZLO swapped dark rounded cards for a square-cornered, paper-and-ink blueprint style. AI review scores work only as a regression list; swapping token values first reskinned 90% of screens in one PR.
Reading
In September 2026, I moved EZLO's website, dashboard, admin console and emails onto a single engineering-blueprint visual style. Two lessons came out of it. AI review scores can't serve as a "must reach X to pass" gate, but the issues the reviewer lists each round are useful as a regression list. And when shipping, the first PR only changed token values, not class or variable names, so 54 files needed no line changes at all and 90% of the screens got the new skin.
The old look was a dark blue-gray background with rounded cards, and it always felt bland to me. Changing only the landing page would have left the app, admin console and emails on the old identity, out of step with the homepage, so the scope was the whole site.
AI scores can't be a gate
I didn't start in code. I explored styles on Claude's Design canvas first. Four directions in the first round narrowed to two, each got a second version, and codex scored them round after round with a fixed prompt. The final direction was the engineering blueprint (D2), and I drew all 96 artboards for the whole site.
D2 went through seven rounds of scoring and stayed stuck between 6.2 and 6.4. To calibrate, I ran the same prompt against Stripe's and Linear's websites, which scored 7.8 and 7.2. This reviewer gives well-known products a little over seven, and that's it.
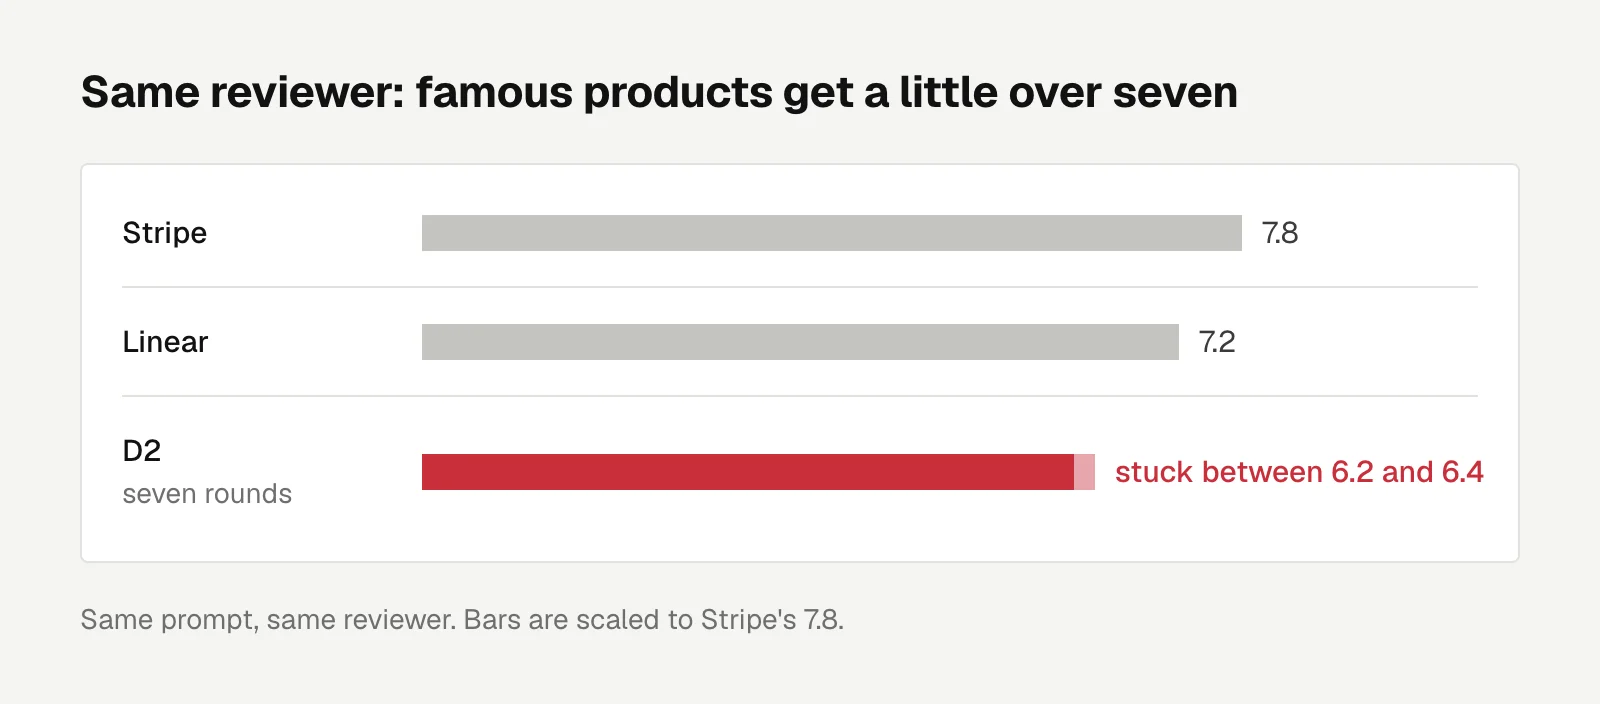
Worse, the top issue the reviewer flagged each round contradicted the one before. One round said the permission-check diagram was too small. After I enlarged it, the next round said it was stealing focus. Scores barely move even after big changes, so as a gate they're meaningless. But working through the issues each round lists, one by one, is very useful.
Swap tokens first, then rework layouts area by area
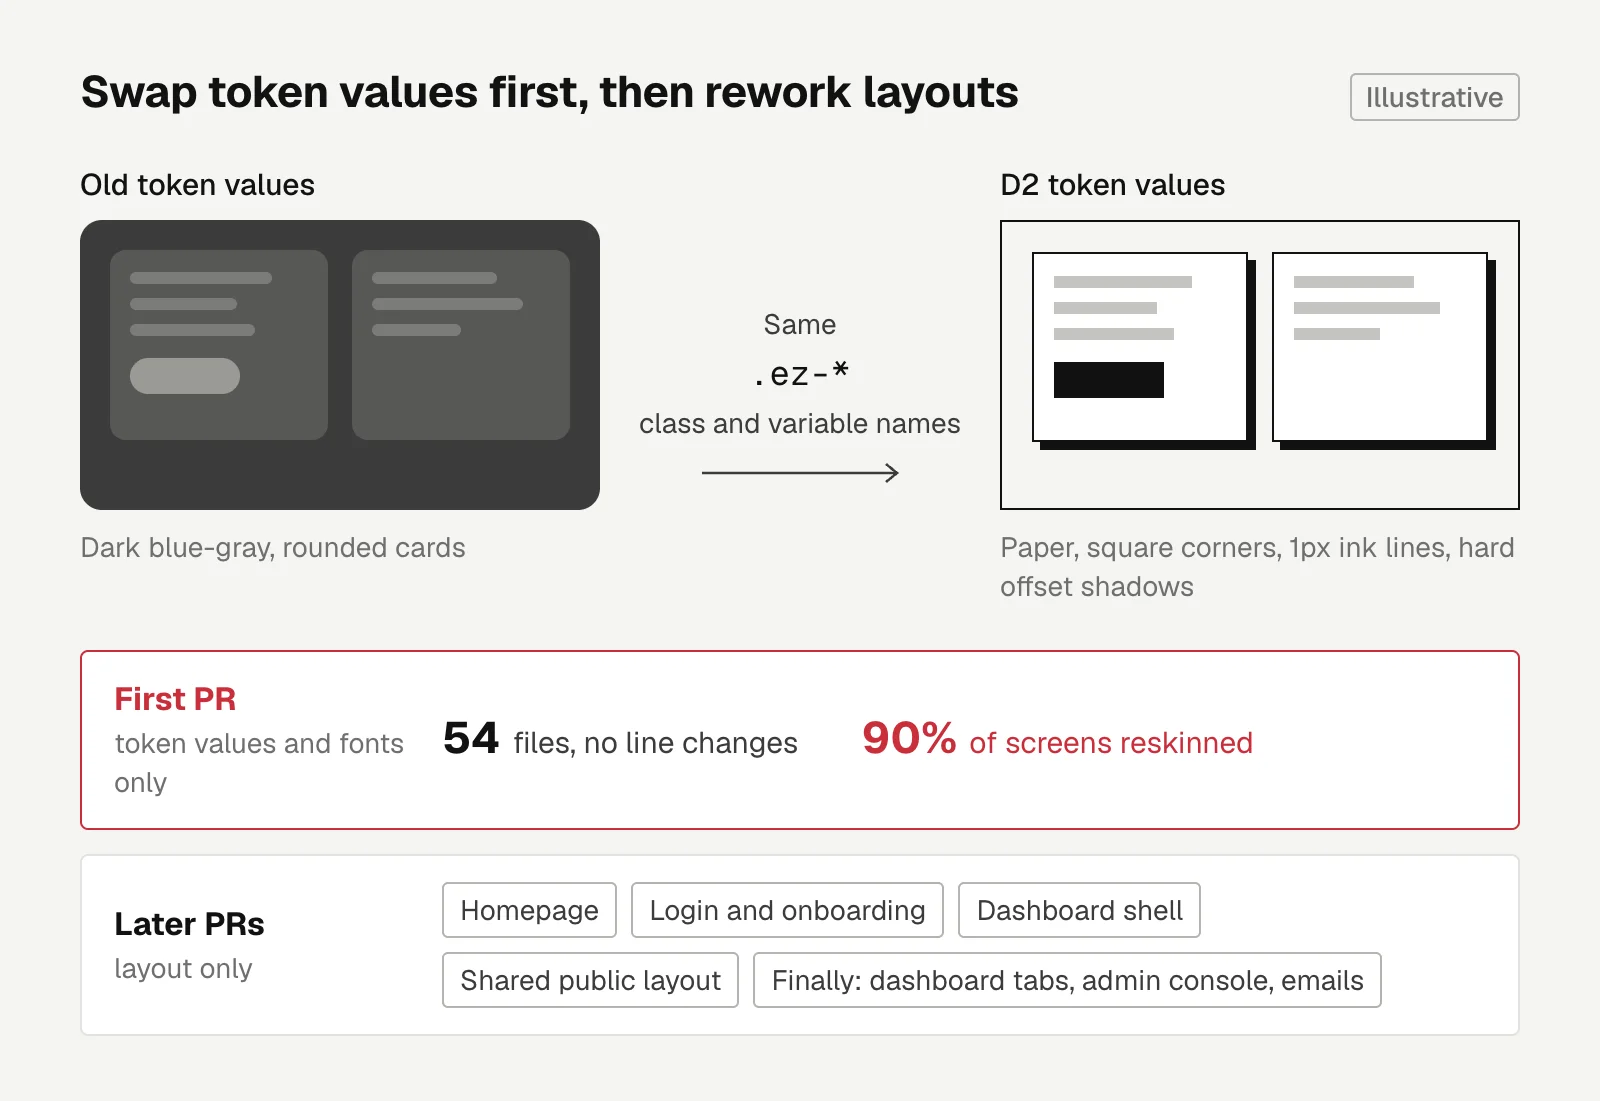
D2's rules are strict, and every color has a job: paper background, ink text, cobalt blue for links and brand, lime only for primary actions with at most one per page, amber only for fund flows and extreme values. All shapes are square-cornered, with 1px ink lines and hard offset shadows. The acceptance criteria also include two accessibility rules: every text token must reach a contrast of ≥ 4.5:1 in both light and dark themes, and there can be no transform animations under prefers-reduced-motion.
The first PR only swapped token values and fonts, and left the .ez-* class and variable names alone. Ninety percent of the screens got the new skin right away, and later PRs only had to deal with layout: the homepage, login and onboarding, the dashboard shell, the shared public page layout, and finally the dashboard tabs, admin console and emails.
The layout work ran in parallel. The main checkout plus two worktrees each ran their own next dev. Each PR went to one Claude Code agent, the shared rules lived in one brief, and artboard screenshots served as the design source. Conflicts only showed up at the end of globals.css and in a few docs. Once I required new CSS to go at the end of its own section rather than at the end of the file, most of the conflicts went away.
What review caught
Every PR got one codex review, plus QA in a real browser logged into my own STG account. Findings from both went into a single fix PR. Some examples: the notification drawer had no focus trap, the background shader didn't stop its rAF after scrolling out of the viewport, and one page had two lime buttons.
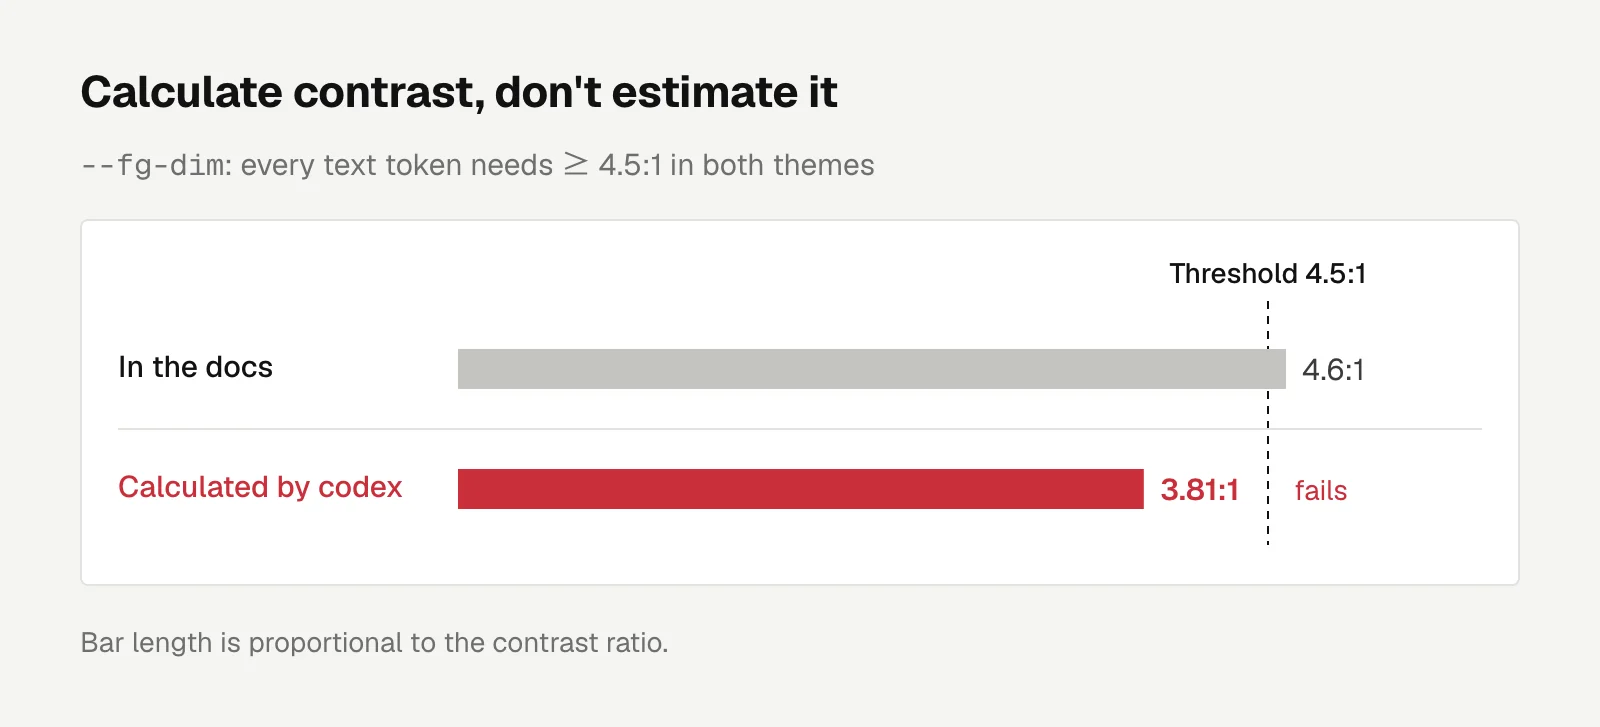
One of them was my own miscalculation. The docs said --fg-dim had a contrast of 4.6:1, and codex actually calculated 3.81:1. Since then, contrast always gets calculated, never filled in by feel.
Another rule: no fake buttons. Some features on the artboards don't exist in the backend, like "Stay signed in for 30 days" or the role-invitation tab in the admin console, and none of them became fake buttons. The permission list is the same. The permissions drawn on the artboard don't fully match what onboarding actually requests, and onboarding wins.
This rule still let one sentence slip through. During the dashboard redesign, the 2FA hint on the settings page described protection the backend didn't have, and it took two days before I fixed it. I wrote about that separately in the account security post.
Wrap-up
- For a full-site redesign, swap only token values first and leave class names alone. One PR changes most of the screens, and later PRs only handle layout.
- AI review scores don't work as a gate, but the issues they list work as a regression list. Calibrate the reviewer against well-known sites before scoring.
- When running agents in parallel, decide up front where each one writes in shared files.
- If a feature is on the artboard but not in the backend, don't build a fake button.
- Calculate contrast. Don't estimate it.
Engineering
How Many Ways Can a Number Input Go Wrong? Clearing Saves 0, Typing e Wipes It
Clearing the reserve field on my lending settings page silently saved 0; this covers string drafts, checking upper and lower bounds differently, the e key in type=number, and per-keystroke input jsdom can't test.
Letters
Loading comments…